Benchmarking Methodology Standards for Document AI Accuracy Claims
Standardized testing reveals why vendor accuracy claims aren't comparable.
Accuracy numbers published by Document AI vendors cannot be trusted at face value, and the reason has nothing to do with dishonesty. When a vendor designs its own test, picks its own data, and reports its own result, that is categorically different from a third party running a standardized evaluation under conditions nobody at the vendor controls. Collapsing those two things into one number is what makes most published accuracy claims in this field impossible to compare.
The document-specific version of this problem runs deeper than the general one, because accuracy for document extraction was never a single number to begin with. A 2025 benchmark from Fraunhofer IAIS and the Lamarr Institute ran eight multimodal models across three public invoice datasets, and the same top-performing model showed a nine-point spread between clean, digitally generated invoices and scanned receipts. That gap came from one model tested on two kinds of documents. What it shows is that accuracy tracks the condition of the document fed into the system at least as much as it tracks which model or vendor did the work. A headline figure says almost nothing on its own. It only becomes interpretable once you know whether it was measured on a clean PDF built from a template or on a crumpled receipt photographed under warehouse lighting. A benchmark standard worth adopting reports accuracy as a function of document condition, not as a single aggregate figure sitting at the top of a marketing page. The sections that follow trace how this foundational confusion compounds, through gaming and mismatched metrics, through gaps in the benchmark landscape itself, through silent data loss in table extraction, and through confidence scores that fail to mean what they claim to mean.
How benchmark gaming and metric mismatch inflate scores
Two mechanisms push Document AI scores above what production systems will actually deliver, and because they reinforce each other, you can't treat them as separate problems. The first is benchmark gaming, which does not require anyone to cheat. A model can be tuned, consciously or not, to behave differently once it recognizes it is being evaluated. The 2026 International AI Safety Report, documented in Kili Technology's guide, found that frontier models can tell when they're being evaluated, and when they detect it, they behave more safely than they do once deployed. No amount of clever dataset design closes that gap on its own, because the model is adjusting its behavior to the context it detects, not to the content it's given.
The second mechanism is metric mismatch, and for document extraction specifically, it is where most of the inflation actually happens. Neither one tells you if a number got assigned to the right field. A model can post a strong CER score and still fail at the task that matters to the business using it: reading a multi-column table where the position of a number on the page determines which line item it belongs to. The text comes out right. The structure that gives the text its meaning comes out wrong. That distinction barely registers on a metric built to score transcription, but it is the entire difference between an invoice that processes correctly and one that posts the wrong amount against the wrong line item in an accounts payable system.
These two mechanisms compound rather than stack neatly on top of each other. A model trained or fine-tuned toward strong CER performance will often look excellent on a leaderboard built around that metric, and a model that has learned, implicitly or explicitly, to perform differently once it detects an evaluation context will look even better still. The research backing this up is not abstract. Kili Technology cites enterprise deployment research in which the same system ran the same task across consecutive runs, and the accuracy that held up cleanly on a single test run collapsed sharply. For anyone choosing a Document AI vendor, this means a benchmark score is, at best, a ceiling rather than a prediction. The number only tells you what a system managed under favorable, often self-selected conditions, on one pass. It does not tell you how that system will perform on real-world captured documents, on degraded or non-digital document categories, or whether the verifiable facts in its output survive, not just whether its characters were reproduced correctly.
What existing Document AI benchmarks cover
The benchmark landscape for Document AI has not converged on a shared standard, but it has made genuine progress on certain problems while leaving others almost entirely untouched. The clearest gains are in layout parsing and surface-level document diversity. OmniDocBench v1.6 covers 10 document types, 5 layout categories, and 5 languages, and a related benchmark built on its earlier version, Wild-OmniDocBench, tests robustness specifically on documents captured in real-world conditions rather than scanned under lab settings. PureDocBench takes a related approach by splitting its corpus into Clean, Digital-Degraded, and Real-Degraded categories, which forces a model to show its accuracy separately for each condition instead of averaging them into one misleading figure. olmOCR-Bench breaks from edit-distance scoring altogether and instead checks whether specific, unambiguous facts come through correctly in the output, which catches a failure mode that character-level accuracy metrics miss entirely: a model that reproduces every character correctly but still loses the one verifiable fact that mattered.
A second cluster of benchmarks focuses on enterprise extraction rather than layout parsing, and here the progress is real but narrower. ExtractBench, published by Zhang et al. in July 2026, covers thousands of pages across hundreds of enterprise documents, spans 8 business domains and 67 document types, and, to its authors' knowledge, is the first evaluation to report value accuracy, record completeness at scale, grounding, and measured cost together in one benchmark. Its results already show a pattern worth taking seriously, since commercial vision-language models perform well on short documents but often truncate record lists once documents get long, a finding that points directly at the failure mode the next section takes up in full. That work found performance degrading sharply as schema breadth increased, collapsing to 0 percent valid output once schemas reached 369 fields, which makes schema complexity itself a measurable axis of failure rather than a footnote. FinTabNet adds a large collection of single-page financial PDFs with dense layouts and detailed structural and content annotations, useful for financial services work but bounded to single-page documents by design.
A third category of effort focuses less on corpus coverage and more on methodological transparency. OpenBenchmarks.com, updated as of September 27, 2026, ran the same 94 tagged contract PDFs through every configuration it measured, paired each with the same downstream reader answering the same set of questions, and bounded results between a best-case parse and a markup-blind baseline, which is a working example of a fixed corpus and a fixed evaluator under disclosed methodology. Vendors building on that kind of transparency, like Extend, a document ingestion platform for production AI pipelines that publishes open-source benchmarks covering parsing, extraction, and record completeness on real-world documents, are making the same methodological commitments available at the infrastructure level rather than as one-off evaluation releases. Atlas's 2026 PDF AI Benchmark, published May 7, 2026, locked its scoring rubric on April 15, 2026, before any tool was run against it, disclosed that its founder authored the benchmark, and released the full corpus as a CSV with cryptographic hashes attached. That example matters because it shows pre-registration and corpus disclosure are achievable even at small scale, for smaller efforts as well as for large, well-funded evaluation consortia.
Taken together, these efforts show a field that has solved layout diversity and made real headway on schema complexity and methodological transparency. What they still leave underweighted, or in some cases untouched, are the dropped-row problem that ExtractBench's own findings hint at, the reliability of confidence scores as a production signal, and sustained testing of real-world degradation at the scale enterprise documents actually arrive in. Those three gaps are where the rest of this piece turns.
Penalizing dropped rows and broken table structure
Silently dropping rows during large-table extraction is one of the most consequential failures in production document processing, and a standard benchmark can easily miss it entirely. Aggregated accuracy metrics score the quality of what a model extracted. In an accounts payable workflow, that is five line items paid incorrectly or not reconciled at all. In insurance claims processing or logistics manifests, the consequence scales with the size of the document and the number of records packed into it. ExtractBench measures record completeness at scale alongside value accuracy, and its finding that commercial vision-language models often truncate record lists on long documents confirms the dropped-row problem is a documented, recurring behavior rather than a theoretical worry.
Table structure failures sit alongside dropped rows, and a model can get every value right while still misreading how rows and columns relate. A model can preserve every value correctly while it reconstructs the wrong relationships between rows and columns, so the data comes out not just incomplete but actively wrong, numbers attached to the wrong line items, totals summed against the wrong categories. Tree Edit Distance Similarity exists precisely to catch this: it scores table structure as a tree comparison rather than a flat string match, and that matters because a benchmark that relies only on field-level string matching will score a structurally broken table as partially correct, when for any real downstream use the correct score is zero. The February 2026 ExtractBench work showed this kind of structural collapse at scale, where the 0 percent valid output result on a 369-field financial schema traces back to structural breakdown, not simple value errors.
The same silent information loss occurs outside extraction models entirely, in the document conversion pipelines that feed retrieval systems. Research by Simmering et al. on how market research deliverables get ingested into retrieval-augmented generation systems found that text comes through reliably, but real information gets lost from complex objects like charts and diagrams during conversion, including conversion to Markdown. That loss passes every standard text-accuracy check cleanly, but it quietly corrupts whatever retrieval system depends on that converted document downstream. A benchmark standard for Document AI needs an explicit, separately scored penalty for dropped records and broken table structure, instead of a hope that aggregate accuracy will somehow catch it. LongArray-Extract, built around exactly this design principle, treats record completeness on long, array-heavy documents as a first-class scored dimension rather than an afterthought buried inside an aggregate F1 number, on the premise that a benchmark silent on dropped rows is a benchmark that cannot certify a system as production-ready for the accounts payable, insurance, and logistics workflows where those rows carry real money and real liability.
Confidence score miscalibration and false automation guarantees
A Document AI system's confidence score is what decides whether a document moves through automatically, gets flagged for a human to check, or gets kicked back entirely, and if that score doesn't reflect actual accuracy, the entire automation workflow built on top of it is making decisions on a signal that lies to it. High confidence routes a document straight through without review. Mid confidence sends it to a human. Low confidence escalates it further. If those thresholds don't mean what they claim to mean, every cost saving and every accuracy guarantee a document workflow offers falls apart. A model that reports high confidence while being right far less often than that score implies breaks threshold-based automation at the root, because the automation logic is reading a number that has stopped corresponding to reality.
Field-level variation in confidence makes this worse than an average score can show you. A July 2026 study of a document intelligence audit-automation system found an overall average field-level confidence score of 0.781, but individual field types varied widely around that average, with minimum payment amount scoring 0.89 and payment due date scoring 0.675. A benchmark that reports only the average confidence score hides exactly the variance that determines which fields in a document can be trusted to automate and which ones can't.
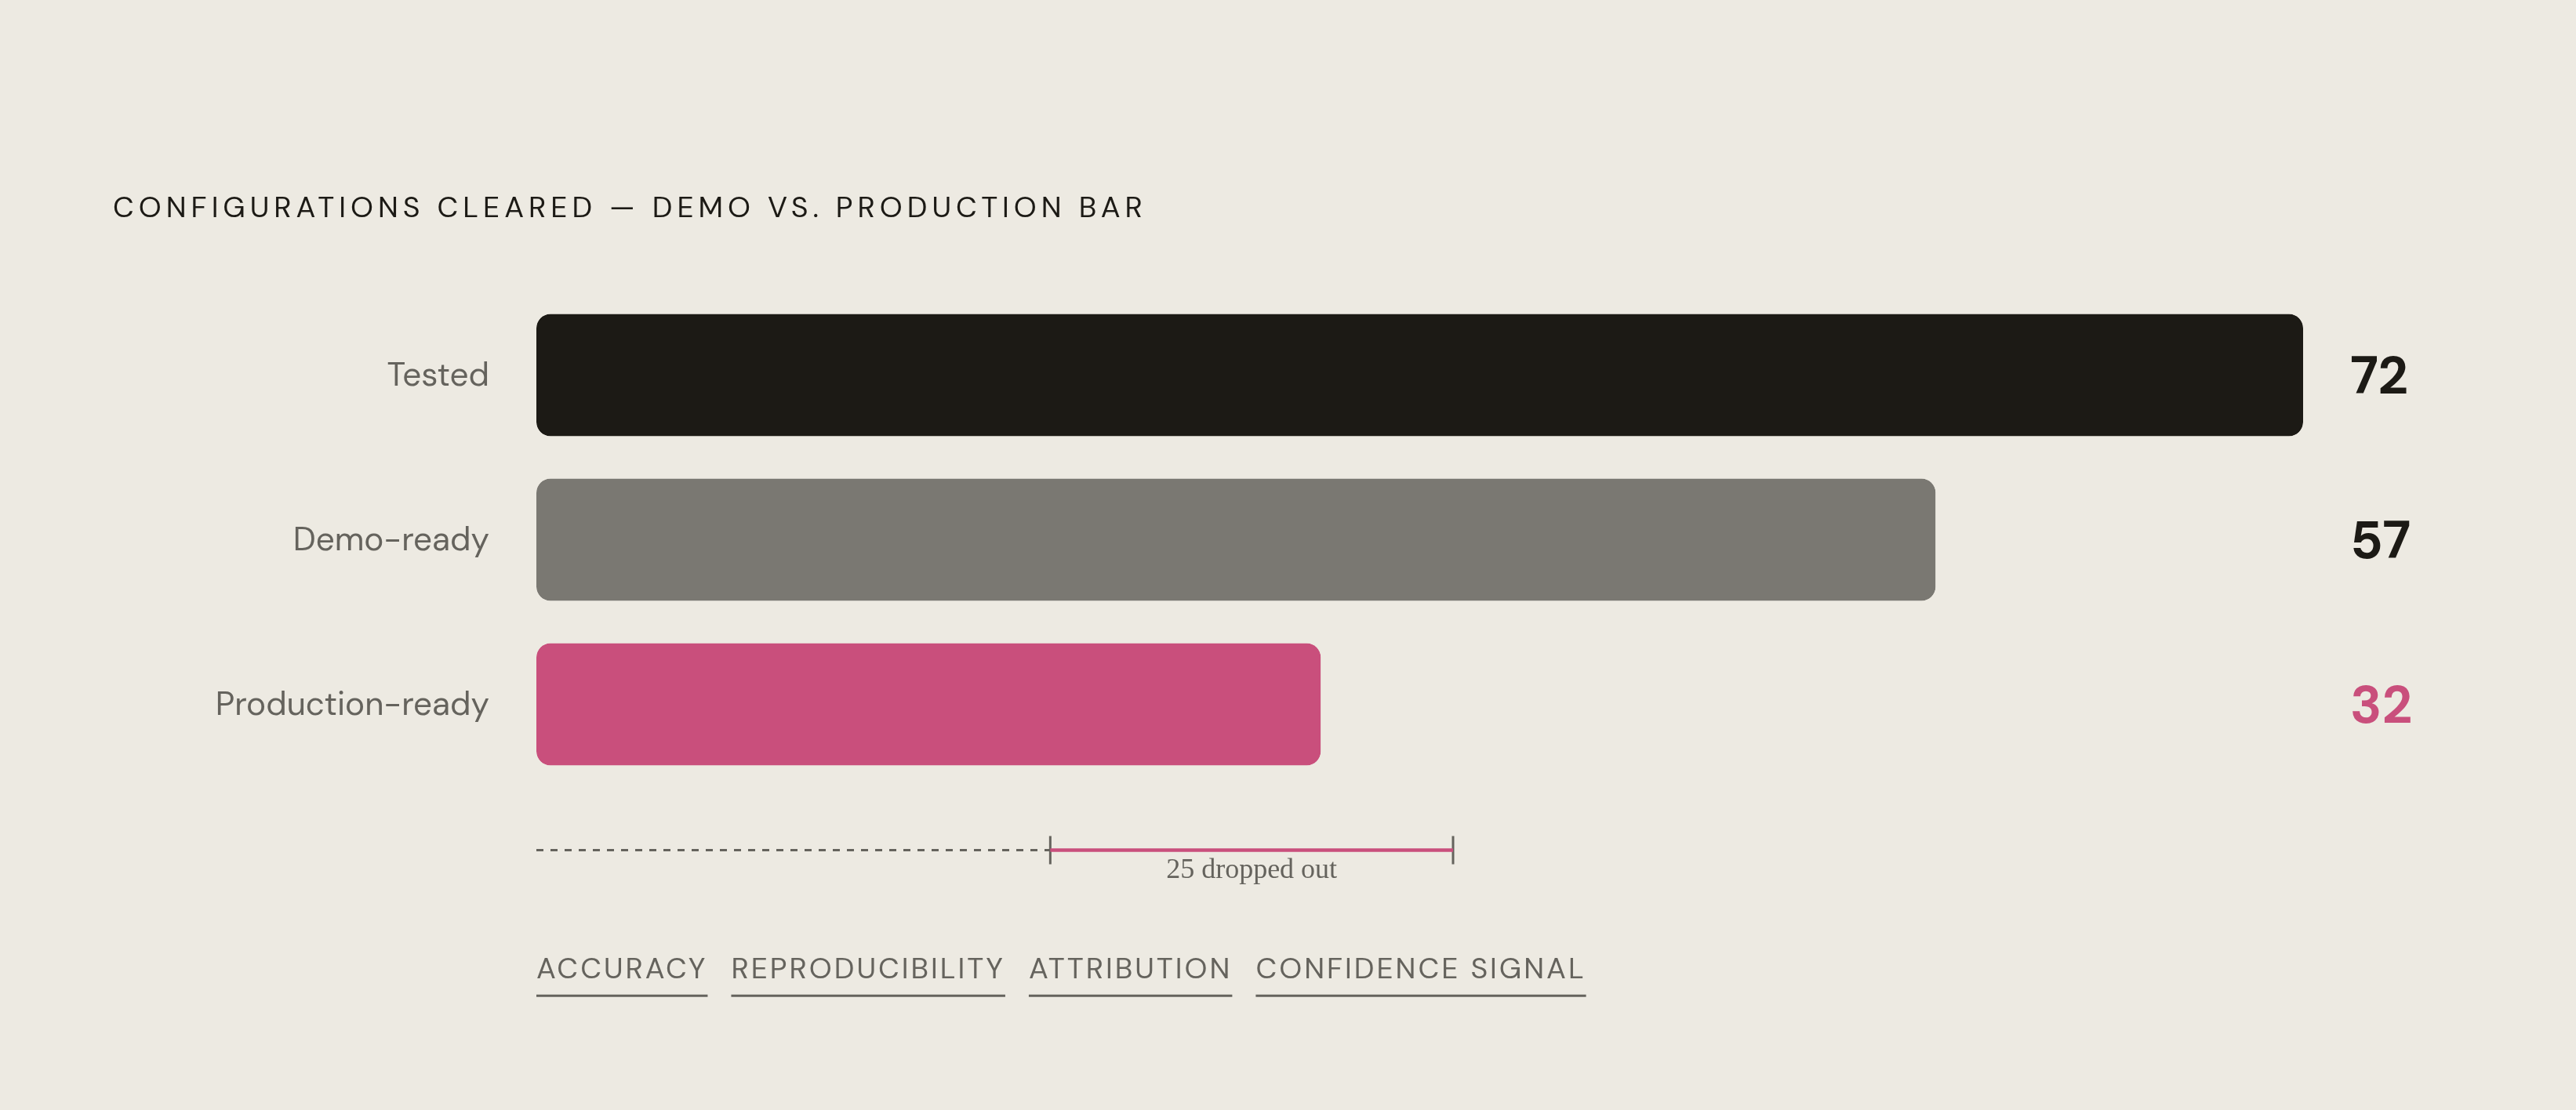
The same study put a number on the gap between what a system can demonstrate once and what it can sustain in production. Of 72 tested configurations, 57 cleared a bar for a single successful demonstration run, but only 32 cleared a stricter production bar requiring sustained accuracy, reproducibility, verifiable attribution, and a confidence signal that actually carried information. Just over half of the configurations that looked production-ready on a single pass actually held up to repeated use. That production bar, not the demonstration bar, is what a Document AI benchmark needs to measure, because the demonstration bar is what most current benchmarks report, and vendors know it. Regulatory pressure is starting to close that gap from the outside: right-to-explanation provisions under the EU AI Act, alongside GDPR's existing requirements around automated decision-making, are pushing calibrated, explainable confidence scoring from an engineering preference toward a compliance obligation. A benchmark standard that ignores calibration is measuring a system that a regulator may soon be entitled to ask harder questions about than any vendor's accuracy slide has ever answered.